Building KVKK and GDPR compliant cloud architectures requires placing data sovereignty, end-to-end encryption, authorisation and audit mechanisms directly at the core of the cloud infrastructure. To meet legal requirements, the geographic location of personal data must be clearly defined, dynamic masking techniques must be applied, and hybrid or multi-cloud models must be configured with a technology-independent approach.
What Is a KVKK and GDPR Compliant Cloud Architecture?
When enterprise-scale companies and financial institutions move their data to modern infrastructures, they cannot think only in terms of performance and cost. Turkey's Personal Data Protection Law No. 6698 (KVKK) and the European Union's General Data Protection Regulation (GDPR) impose strict rules on how personal data is processed, stored and transferred. Integrating these rules into the technical infrastructure is what we call a compliant cloud architecture.
Core Requirements of the Regulations
Both KVKK and GDPR mandate the principles of confidentiality, integrity and availability. At the architectural level, these principles require protecting data against unauthorised access, verifying data integrity and having backup mechanisms that ensure business continuity in the event of a disaster.
The Importance of Technology-Independent Design
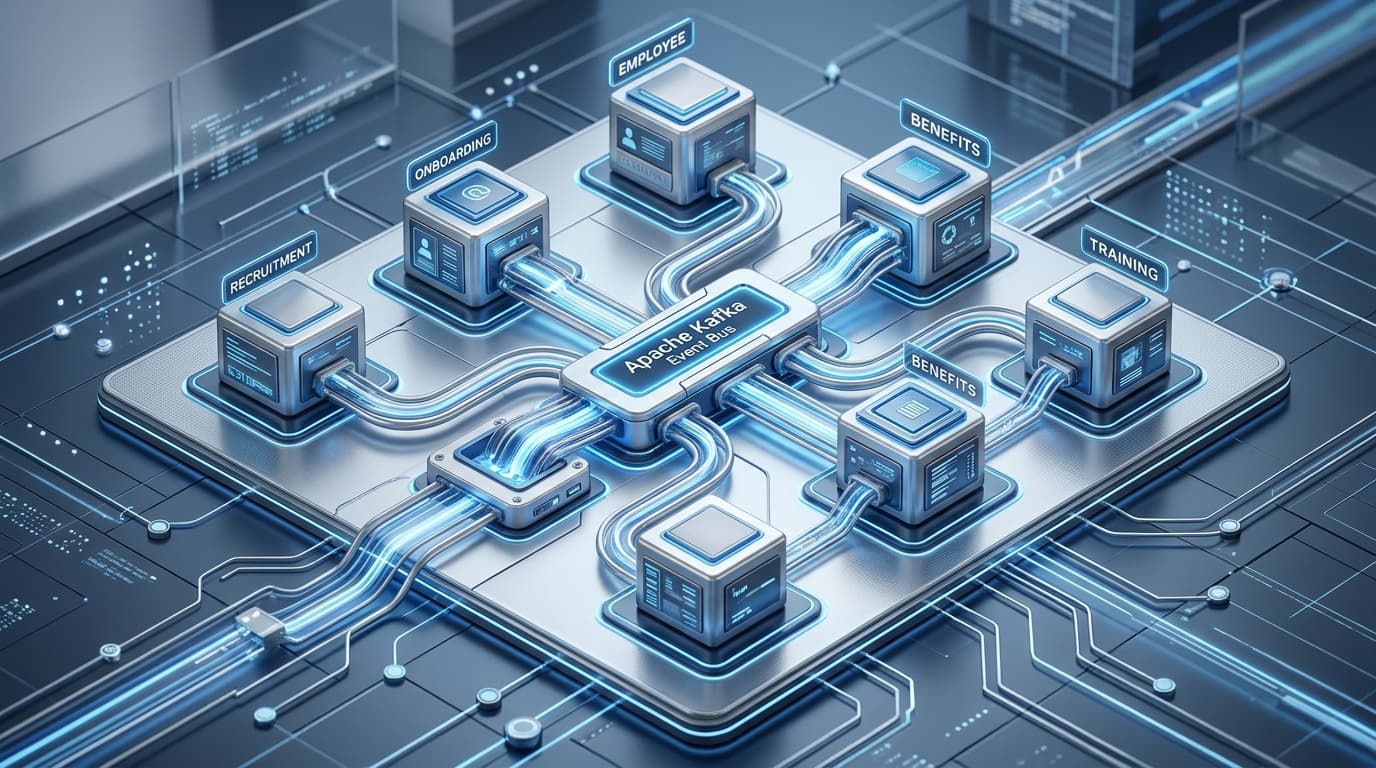
Avoiding lock-in to a specific cloud provider (such as AWS, Azure or GCP) is critical for long-term regulatory compliance. A technology-independent approach preserves the organisation's agility against data residency requirements that regulators may introduce in the future. A well-designed cloud solutions strategy allows workloads to be moved between on-premise data centres and the public cloud according to regulations.
Core Regulatory Principles in Cloud Architectures
There are two fundamental pillars that must not be overlooked when building a data architecture in cloud environments: the volume of data processed and geographic boundaries.
Data Minimisation and Purpose Limitation
Every byte of data transferred to the cloud is a liability. Under the data minimisation principle, only the data required by the business process should be collected and stored. Raw data transferred to the data warehouse or data lake should be filtered out in the parsing layer. A sound data management strategy prevents unneeded sensitive information from reaching the analytics layers.
Data Residency and Cross-Border Data Transfer
Article 9 of KVKK and Chapter 5 of GDPR subject the transfer of data outside national borders to strict conditions. Regulations in Turkey encourage or require that banking, healthcare and public sector data in particular be kept within the country. Accordingly, hybrid models integrated with local data centres, or architectures in which data is processed and anonymised before being transferred to the public cloud, should be preferred.
Technical Security Measures in the Architecture
Regulatory compliance is not limited to administrative policies; it must be implemented directly in the software and network layers.
End-to-End Encryption and Key Management (KMS)
Data must be protected with strong encryption algorithms (at least AES-256) both in transit and at rest. The critical point here is key management (Key Management Service - KMS). In practice, 'Bring Your Own Key' (BYOK) or 'Hold Your Own Key' (HYOK) approaches should be preferred over the default encryption keys offered by the cloud provider. This way, not even the cloud provider itself can hold the key.
Data Masking and Anonymisation
Sensitive data must be masked, especially in the layers where analytics teams and business intelligence tools operate. While data flowing through big data platforms is processed in real time, fields such as Turkish national ID numbers, credit card details or names should be transformed using tokenisation or pseudonymisation methods.
Zero Trust Based Access Controls (IAM)
In cloud architectures where network perimeters disappear, the 'never trust, always verify' (Zero Trust) model is mandatory. Role-based access control (RBAC) and the principle of least privilege must be applied. Every service, user and microservice API call must go through authentication.
KVKK and GDPR Compliance Comparison Matrix
The table below summarises the technical and structural differences between the two core regulations that directly affect cloud architectures:
Criterion | KVKK (Turkey) | GDPR (European Union) | Recommended Architectural Solution |
|---|---|---|---|
Cross-Border Data Transfers | Requires Board approval, a written undertaking or explicit consent. | Adequacy decision, BCRs or standard contractual clauses. | Hybrid cloud set-up; only anonymised data transferred across borders. |
Right to Be Forgotten | Obligation to delete, destroy or anonymise data. | Right to request erasure of personal data (Article 17). | CDC (Change Data Capture) and ID-based hard delete flows in the data lake. |
Data Breach Notification | To the Board and the data subject within 72 hours at the latest. | To the supervisory authority without undue delay, where feasible within 72 hours. | SIEM integration, automated logging and real-time anomaly detection. |
Privacy by Design | Recommended in the guide on administrative and technical measures. | Legal obligation (Privacy by Design - Article 25). | Masking data at the moment it is first collected in the microservice architecture. |
Building a Compliant Cloud Infrastructure Step by Step
Transforming an enterprise system into a fully compliant cloud architecture takes place in three main phases.
Phase 1: Data Inventory and Classification
The first step is mapping all of the organisation's data assets. Automated scanning tools should identify which table contains identity data and which log file contains IP addresses; data should then be labelled as 'Public', 'Internal', 'Confidential' and 'Strictly Confidential/Sensitive'.
Phase 2: Hybrid or Multi-Cloud Design
While sensitive data is kept on-premise, workloads that require scalable compute power can be distributed to the public cloud. When building data pipelines, anonymisation with dedicated algorithms must be completed before the data leaves the on-premise layer.
Phase 3: Continuous Auditing and Monitoring
All data movements, permission changes and read/write requests in the cloud environment must be kept in immutable log systems. Audit logs should be retained for at least 2 years and cryptographically locked against unauthorised queries.
Industry Practices and Common Mistakes
Experience from projects at large organisations shows how theoretical approaches break down in the field.
Challenges in Banking and Finance
In the banking sector, BDDK and KVKK regulations contain rules that complement each other but are operationally demanding. Transferring data that qualifies as bank customer secrets directly to the public cloud is restricted. In such structures, when banking software is developed, the core database is kept locally; only synthetic data required for machine learning or analytical modelling is sent to cloud compute clusters.
The 3 Most Common Architectural Misconceptions
Over-Relying on the Cloud Provider: Cloud providers are responsible for the security of the infrastructure (Security OF the Cloud); the security of the data within that infrastructure and regulatory compliance (Security IN the Cloud) are entirely the customer's responsibility.
Forgetting Development and Test Environments: While all security measures are taken in production, moving unmasked data copied from production to test environments in the public cloud is a major source of breaches.
Overlooking Backup and Disaster Recovery Data: Even if the production database is encrypted, keeping backups unencrypted or mistakenly placing geo-backups in a region located in a non-compliant country is a common mistake.
Building fully compliant, flexible and high-performance cloud infrastructures is the most critical step in an organisation's data-driven growth. Let's work together on your project. Get in Touch.
Frequently asked questions
Is the use of public cloud prohibited under KVKK?
No, KVKK does not prohibit the use of public cloud altogether. However, if the cloud provider's data centres are located abroad, this is treated as a transfer of personal data abroad, and the conditions in Article 9 of the law (explicit consent, a written undertaking or standard contracts) must be met.
How is GDPR's right to be forgotten technically implemented in a cloud architecture?
For the right to be forgotten, data warehouse and data lake architectures use 'Change Data Capture' (CDC) methods and table formats with ACID support (Delta Lake, Apache Iceberg). Records belonging to the relevant user's ID are permanently deleted from all analytical tables within the defined legal period.
What is the architectural difference between data masking and anonymisation?
Masking is usually applied dynamically; authorised users see the original data while unauthorised users see the masked version (for example, hiding the first 12 digits of a credit card). Anonymisation, by contrast, is the irreversible de-identification of data, and data that has been anonymised falls outside the scope of the regulations.
Is the standard encryption offered by cloud providers sufficient for enterprise compliance?
For most regulated sectors, provider-managed keys are not considered sufficient. BYOK (Bring Your Own Key), where control of the encryption keys rests entirely with the company, or hardware HSM modules should be used.
Which approach should banks prefer in cloud architecture?
Banks and critical financial institutions mostly prefer the hybrid cloud model for regulatory compliance. Sensitive customer data and core banking systems are hosted on on-prem infrastructure, while risk models or analytical workloads run on private or public cloud clusters using anonymised data.