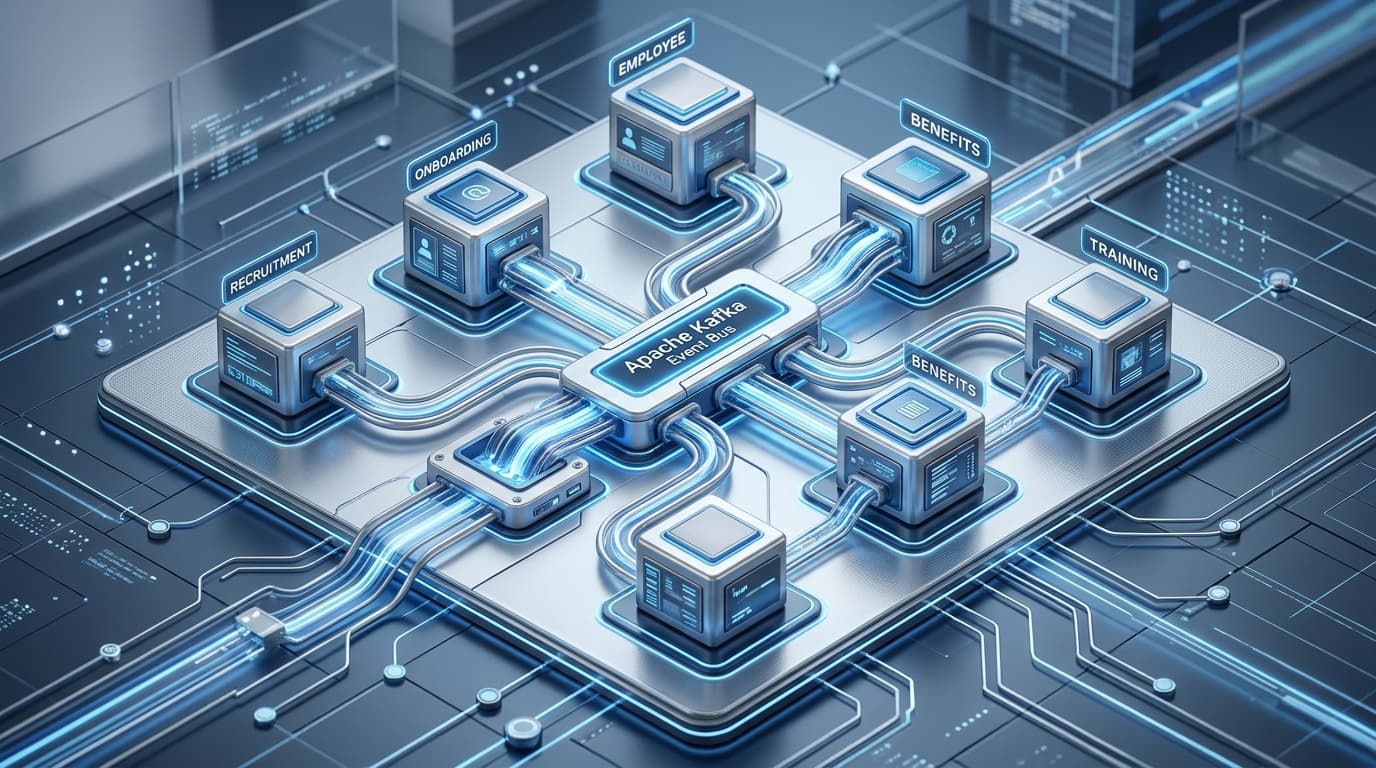
Scalable HR systems with microservices architecture and Kafka workflows means splitting processes such as payroll, leave, recruitment and performance into independent services and connecting them through event-based, asynchronous communication. This way, a spike in load or a failure in one service does not stop the others, and each process grows according to its own needs.
Why Does a Monolithic HR System Hit Its Limits?
In single-block HR software, payroll calculation, leave approval and personnel records share the same database. During the month-end payroll peak, the leave screen slows down too. Even a small change requires redeploying the entire application. As the organization grows, this approach creates problems in both speed and reliability.
- A single bug can affect all modules.
- It is not possible to scale only the module under heavy load.
- Integrations with systems such as SAP, Logo or Netsis become tightly coupled.
- For any new feature, all teams depend on the same release calendar.
How to Design Scalable HR Systems with Microservices Architecture and Kafka Workflows?
The first step is to draw service boundaries along business domains. Each service owns its own data and never accesses another service's database directly. This principle is consistent with the independent deployment logic described in Martin Fowler's microservices article. When drawing boundaries, the answer to the question "if this data changes, which team is responsible?" should be clear.
Example service split
| Service | Responsibility | Event it publishes |
|---|---|---|
| Personnel service | Employee records and organizational structure | EmployeeHired, EmployeeTransferred |
| Leave service | Leave requests and approval flow | LeaveApproved |
| Payroll service | Salary and deduction calculation | PayrollCalculated |
| Recruitment service | Candidate pool and offer process | OfferAccepted |
| Notification service | Email and in-app notifications | Consumes events |
The role of Kafka
In this architecture, Kafka works as both a message queue and a durable event log. A service publishes an event, and interested services read it at their own pace. Because topics are divided into partitions, the number of consumers reading the same topic can be scaled out horizontally as load increases. Using the employee number as the message key is a common way to preserve the order of events belonging to the same employee. For technical details, the official Apache Kafka documentation is the right reference.
How Does the Asynchronous Flow Work in Practice?
Let's take the onboarding of a new employee. The process runs through the following steps:
- The recruitment service publishes the OfferAccepted event, and the personnel service creates the record.
- The personnel service writes the EmployeeHired event to the relevant Kafka topic.
- The payroll service reads the event and opens the salary record.
- The leave service defines the annual leave entitlement.
- The notification service sends a message to the manager and the employee.
The personnel service does not wait for the others' responses. Even if the payroll service is temporarily down, the event is not lost; when the service comes back, it resumes where it left off. Whereas in the old structure a single error would reject the entire onboarding, here only the relevant step is retried.
Error Handling and Data Consistency
In a distributed system, not every step will succeed. At this point, instead of one big transaction, you need flows with compensating steps. The Saga pattern describes this approach: if one step fails, the previous steps are rolled back.
- Idempotent consumer: If the same message arrives twice, the result must not change.
- Dead letter topic: Messages that cannot be processed are moved to a separate topic and reviewed.
- Retry policy: For transient errors, controlled retries are performed.
- Observability: A process ID is kept for every event, so the source of an error can be found quickly.
In practice, the most common mistake is designing events only for the "success" scenario. For flows that involve money, such as payroll, we recommend first mapping out the failure scenarios, that is, the rollback and reprocessing steps. This practice is the most valuable lesson from our experience with enterprise data platforms.
Security and KVKK Compliance
HR data is personal data. Event payloads should carry only the necessary fields, and sensitive information should be masked or transferred via an identity reference. Access permissions are defined per service, and logs are kept auditable. To trace the data flow, you can take a look at our guide to data lineage and data trust. We also recommend following the official KVKK website for personal data protection obligations.
Things to Watch Out for During Implementation
- Start small: first separate a low-risk service such as notifications or leave.
- Version your event schemas; add fields without breaking consumers.
- Instead of abandoning your existing SAP, Logo or Netsis infrastructure, generate events through an integration layer.
- Set up monitoring and alerting from day one.
- Decide early whether you will run the infrastructure in the cloud or in your own data center.
Rather than migrating all at once, moving forward module by module with the "strangler" approach reduces risk. At each step, run the old and new flows in parallel for a while and compare the outputs; shut down the old module only once the results are consistent. Also clarify the division of responsibility between teams from the start: each service should have an owner, an on-call plan and documentation.
BIART Bilişim offers a technology-agnostic approach with Kafka-based big data platforms, cloud solutions and custom software development services. You can see our experience in enterprise projects on our references page. Let's work together on your project. Get in Touch.
Frequently asked questions
Is microservices architecture a must for HR systems?
No. A single-block structure may be sufficient for small organizations with a stable load. Microservices make sense when modules grow at different speeds and independent releases are needed.
What is Kafka used for in HR processes?
It provides event-based, asynchronous communication between services. Even if a service is temporarily down, messages are stored and processed later.
Should we abandon our existing SAP or Logo system?
No need. The existing system can produce events through an integration layer, and new services can consume those events.
How is data consistency ensured?
Consistency is managed with Saga-style compensating steps, idempotent consumers and dead letter topics.
What should be considered for KVKK compliance?
Events should carry only the necessary fields, sensitive data should be masked, and per-service access control and audit logs should be maintained.