Enterprise AI consulting: auditable, secure and grounded in your data
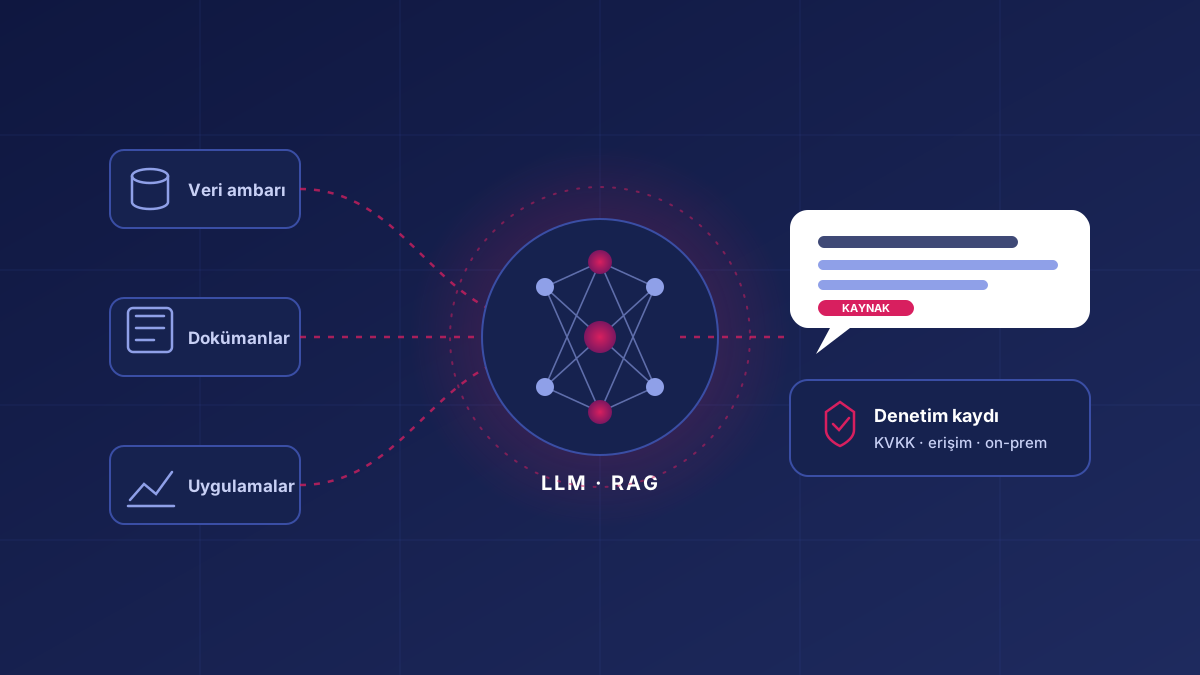
BIART's enterprise AI consulting is for banks and large organizations that want to take generative AI (GenAI) and large language models (LLMs) beyond experiments and into production safely. When we build enterprise AI solutions, we put the organization's data, processes and regulatory limits at the center rather than the model. The result is AI applications that rely on correct data, show their sources, log who accessed what and, when required, run entirely on-premises.
When do organizations work with us?
- Leadership expects a concrete generative AI use case and business case, but it is unclear where to start.
- You need an assistant that answers questions over internal documents, procedures and policies (RAG).
- Customer data or confidential information cannot be sent to public cloud AI services, so an on-prem LLM is required.
- An existing chatbot or LLM pilot gives wrong, unsourced or inconsistent answers.
- Analysts and managers want to ask questions of their data in natural language without writing SQL.
- Compliance, risk and internal audit ask how AI usage will be monitored and constrained.
What you gain
- Reliable answers
responses grounded in your data and documents, with sources shown.
- Data sovereignty
model and infrastructure options that keep sensitive data inside the organization.
- Auditability
every query, source used and model decision is logged.
- Measurable value
use cases tracked against success metrics defined per process.
What we deliver
- AI strategy and use-case workshop
a list of scenarios prioritized by business value, data readiness and risk.
- LLM integration
connecting large language models to CRM, contact center, document management and internal portals through APIs and events.
- RAG-based enterprise assistants
document processing, vector search, permission-aware retrieval and source citation.
- On-prem LLM infrastructure
in-house model serving with open-source components such as Ollama, vLLM and TEI, GPU capacity planning and monitoring.
- Enterprise chatbot and AI agent development
employee and customer assistants, and agents that run workflows step by step with human approval points.
- Natural-language questions over data (Text-to-SQL)
auditable SQL generation with a semantic layer and permission checks.
- MLOps and model lifecycle
versioning, monitoring and retraining of forecasting, scoring and anomaly models.
- AI governance
usage policies, personal data masking, prompt and output controls, and evaluation sets.
Our approach
- Discovery and prioritization
use cases, data sources, users and regulatory limits are defined together.
- Data and architecture readiness
source data quality is measured; the model, hosting environment and security architecture are chosen.
- Controlled pilot
tested with a limited user group against predefined accuracy and adoption metrics.
- Production rollout
authentication, authorization, logging, cost and performance monitoring go live.
- Continuous improvement
answer quality is measured regularly with evaluation sets; new use cases are added on the same platform.
Engagement models
- Project-based delivery
assistant, integration or platform projects with scope and acceptance criteria defined up front.
- Team augmentation
LLM, data and MLOps engineers working inside your AI or data team. See our outsourcing service for details.
- Managed service
monitoring of AI applications in production, model updates and user support.
Why BIART?
- Technology independence
we are not tied to one model vendor; we recommend open-source, commercial and cloud models based on need, cost and data sensitivity.
- Data trust first
AI is only as good as its data. With our own product CentraQL we built an AI Copilot that measures data quality, tracks lineage and answers natural-language questions in an auditable way, and we bring the same approach to client projects.
- Banking and regulated-industry experience
KVKK, GDPR and BDDK requirements, personal data masking and access logging are part of the architecture from day one.
- End-to-end capability
with our data management, big data and custom software teams we connect AI to your existing systems.
- Istanbul and Baku teams
we run projects in Türkiye and Azerbaijan with local teams, in Turkish, Azerbaijani, English and Russian.
How is pricing determined?
Every AI project is different, so we prepare a scoped proposal instead of a fixed price list. The main factors are:
- Number and complexity of use cases
a single document assistant, or agents connected to several systems?
- Data sources
document volume, structured sources and data readiness.
- Hosting environment
on-prem GPU infrastructure, private cloud or managed model services.
- Security and compliance requirements
masking, access control, logging and audit scope.
- Users and usage intensity
model call volume and performance expectations.
- SLA
support hours, response expectations and managed service scope.
Related reading
- 3 ways to integrate LLMs into enterprise processes
- RAG architecture: grounding LLMs with enterprise knowledge
- On-prem LLM strategy for banks: Ollama, vLLM and TEI
- AI agents in enterprise workflows: five scenarios
- KVKK 2026 and AI applications: a compliance roadmap
Take AI to production with confidence
Let's review your use cases, data and regulatory limits together. Contact the BIART team to define the right starting point and engagement model for your organization.